Subsetting: not the whole database, just part of it
Subsetting moves a coherent, dissociated slice of a production database into test environments, with less data volume and shorter load times.
In previous posts we saw how our tool can transform real data into data that is not real but looks real, so that it can be used in non-production environments such as QA or development. Now we present a new feature that, in our experience, is very useful when databases hold large volumes of information, much of which is unnecessary for certain purposes.
To understand why this feature is so useful, we first need to understand the problem we want to tackle. Suppose we are working with databases of customers who buy or subscribe to services from a company, and we want to prepare a dissociated environment for the QA and development teams to work on. The production database will hold many customers, each with their products/services and other associated data. However, non-production environments probably do not need the complete database: having customers that meet certain scenarios is enough, and not all the records of those selected customers may be needed either.
Let’s look at an example. In a test case that needs a customer with only one contracted service, in order to test the feature that adds an extra service at a customer discount, the QA database does not need every customer that meets this condition, let alone every customer whether or not they meet it. Having one of them, or a subset, is enough.
Our proposal, therefore, is to move a coherent subset of the database (or of part of it), starting from a root table or entity from which the related data in the rest of the database’s entities is obtained and transferred to another database with the same structure. In addition, the dissociation of sensitive information is carried out during the transfer of coherent data to ensure the protection of customer information.
As a result, the new database holds dissociated data and is no larger than necessary, which brings advantages such as faster replication and/or restoration of its data, shorter load times through the selective dissociation process, smaller data volumes, and easier access to useful data.
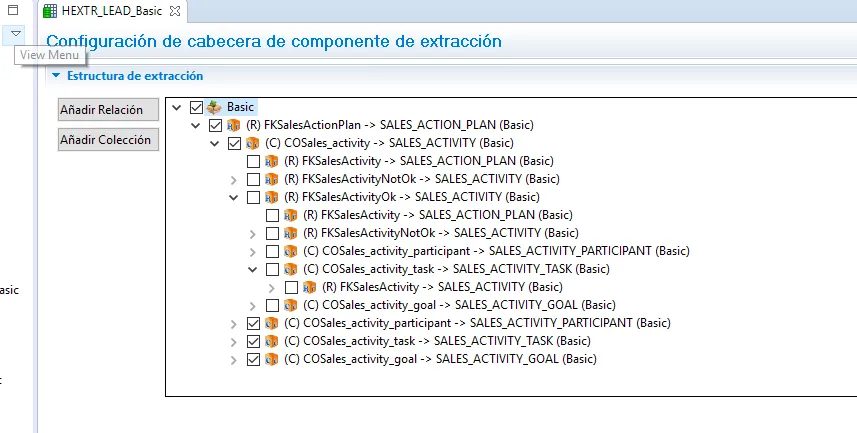
Image. Configuring the extraction path.
This solution looks like a good alternative until we come across catalog entities that other entities refer to. Here, catalog entities are entities that provide general information, such as the catalog of products or services offered by the company. They therefore need to be transferred in full, and there is no need to do so by traversing the schema’s relationships, which lowers the performance of the process compared with transferring the whole table. As a result, our application not only lets you define different trees from roots, but also lets you mark the entities that must be transferred in full.
Taking selective dissociation to the extreme, in icaria TDM we have implemented an additional feature: the mailbox. It is a tool designed to run subsetting for a very small number of seeds. In other words, if a customer has been found in production that needs to be moved to the other environment, instead of running the complete process we could create a request in icaria TDM to move and dissociate that customer, through an interface that is very easy to use for any user regardless of their training on the platform. It also has the advantage of being a tightly scoped method, which allows data owners to give access to a larger number of users.
As we have seen, these options are useful and necessary depending on the characteristics of the installation and the preferences of the users. Limited space is one of the most common problems we encounter, and subsetting is the ideal solution to overcome it, making the most of the available resources. Two out of three dissociation projects with icaria TDM require it. We usually test it during the proof of concept, so much of the information needed is already available and in the hands of the client’s team for review. However, the paths used to obtain coherent data need to be fine-tuned.
Conceptually the idea is simple, but defining it is relatively laborious: the data model is usually not well known and adequate documentation is not available. Perhaps we can offer our clients some help. It is time to create and test a new icaria TDM plugin whose goal is to discover relationships between data.